A useful observation programme begins with a decision that somebody can act on. Before selecting imagery or instruments, define the area of interest, the people responsible for inspecting it, and the time available for a response. This planning perspective connects remote measurements with the practical questions that shape a survey or monitoring service. The aim is to identify which observations would change a decision, how supporting evidence would be collected, and what should happen when information is incomplete. A clear plan makes later technical choices easier to assess against an operational purpose.
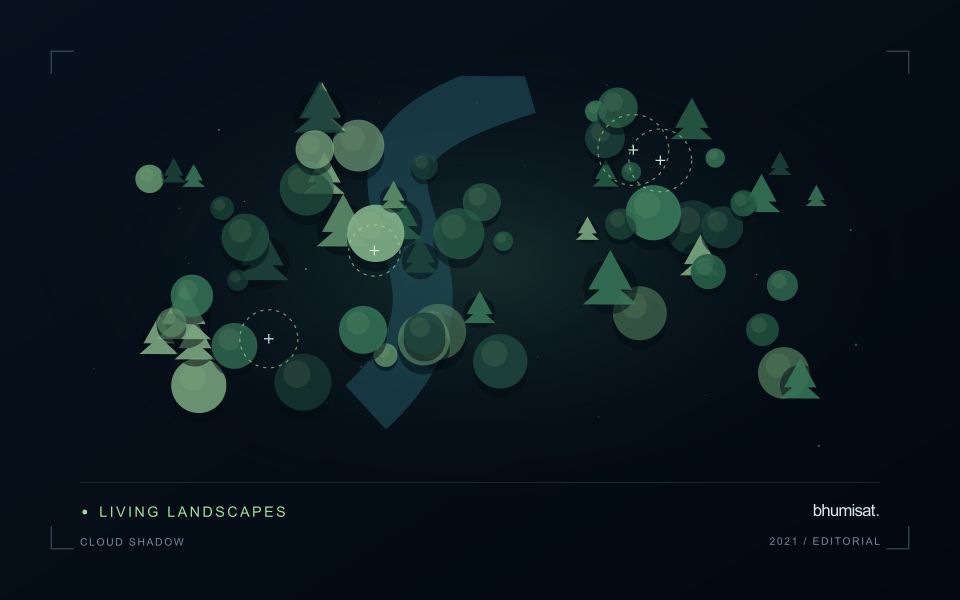
This working guide considers cloud and shadow screening for optical imagery around forest fragment edges. The immediate decision is to investigate changes near forest boundaries. Useful reference evidence includes edge locations, neighbouring land use and canopy inspections. The case is an illustrative planning context, with assumptions to check against the actual sensor, landscape and project requirements.
The setting: Forest fragment edges
A forest fragment is influenced by the land covers and activities around its boundary. At image scale, an edge observation may combine trees, fields, roads, buildings or exposed ground. A change in that mixture can be important, but it should not automatically be interpreted as a change within the forest interior. Define the monitoring unit and distinguish questions about boundary movement, canopy condition and the surrounding land-use pattern before selecting a method.
Geometric consistency is particularly important where a narrow strip or a small patch is being compared between dates. A slight shift in an image or boundary can change the proportion of forest assigned to an observation. Review alignment and use measurements suited to the actual patch size. Retain information about cloud quality, valid coverage and acquisition dates, especially where a proposed change is supported by only a small number of observations.
Field validation should sample edge and interior settings separately when their interpretation differs. Record neighbouring land use, the position of the observed boundary and any evidence of recent disturbance or management. A general vegetation score cannot establish the ecological condition of a fragment on its own. A practical product can help identify boundary changes and inspection priorities, while more specific conclusions about habitat or forest health require measurements designed to address those outcomes directly.
A quality mask changes the evidence available
Clouds and their shadows can produce strong changes in optical imagery that have little to do with the condition of the land beneath them. A quality mask identifies observations that should be excluded or treated cautiously for a particular analysis. It is not simply a cosmetic step used to improve an image. The mask determines which measurements contribute to an index, field statistic or time-series model. Its assumptions therefore belong in the analytical record and should remain available when a result is reviewed.
A scene with a low overall cloud percentage can still be unsuitable for a particular farm. Conversely, a partly cloudy scene may contain useful observations over the target fields. Evaluate quality at the area of interest rather than relying only on scene-level metadata. Cloud edges, haze and shadow boundaries can be difficult to classify consistently. Depending on the application, an additional exclusion around a flagged feature may be appropriate. The effect of that choice on usable coverage should be measured instead of hidden.
Check the mask as part of the result
Inspect representative successful and unsuccessful cases before adopting a mask rule across a large archive. Check whether bright soil, roofs, water or dark vegetation are being confused with cloud or shadow. Compare automatic flags with image context and, where available, independent observations. A mask that removes too much valid data can be harmful, while one that retains contamination can create false alerts. The acceptable balance depends on the downstream task and the costs of missed observations and misleading interpretations.
Each delivered field result should state the acquisition date and the fraction of the relevant area supported by valid measurements. If too little remains, a missing result can be more informative than a precise-looking number based on an unrepresentative fragment. Keep observation gaps visible in charts and maps. When the masking method or product version changes, assess how the update affects historical comparability. Treating cloud and shadow screening as part of the evidence chain makes the final agricultural or environmental interpretation easier to audit and more dependable in practice.
Design an evaluation that reflects deployment
A model evaluation should resemble the conditions in which the model will be used. Start by identifying which relationships the development data share: nearby locations, repeated observations of the same unit, common collection teams, or measurements from a single period. These relationships can make records less independent than they appear. An evaluation that ignores them may test the ability to recognise familiar conditions rather than the ability to operate in a new setting.
Choose a split strategy that matches the intended transfer. Holding out locations, seasons, operational units, or acquisition conditions can answer different questions. Document which question each split is designed to address, and keep the held-out evidence separate while selecting features and tuning the method. Repeatedly inspecting the same evaluation set to improve a model gradually makes that set part of development, even if it retains its original label.
Report results at a scale that is meaningful to the user. A strong average can hide poor performance for important subgroups or unusual conditions. Examine error patterns and retain examples of both successful and unsuccessful predictions. Where the evidence covers only a limited range of conditions, describe that range explicitly. The evaluation then becomes a practical guide to suitable use, further testing, and the collection of additional reference observations.
Define a representative reference sample
A reference sample should represent the situations in which a method will be used. Begin by defining the target population: locations, time periods, management conditions, surface types, or instrument states that belong within the intended application. A collection of convenient observations may be valuable for exploration, but it does not automatically support conclusions about that wider population. Make the scope of the sample visible before calculating a summary of performance.
Consider a stratified design when important conditions are unevenly represented. Relevant strata might include different landscape types, developmental stages, observation quality levels, or ranges of the variable being estimated. Choose sample locations within those groups using a documented rule, and retain the information needed to understand their selection. Where access restrictions affect the sample, record the excluded conditions so that the limits of the resulting evaluation remain clear.
Keep development and evaluation evidence separate where the purpose of the study requires an independent test. Nearby observations or repeated measurements can share information, so a random split of individual records may overstate independence. A split organised by location, period, or operational unit can provide a more demanding comparison. The appropriate design follows the intended deployment, the structure of the observations, and the errors that matter to the user.
Bring the evidence back to the decision
The practical outcome should be a short observation plan that another team can follow. It should name the decision, the required evidence, the responsible roles, and the conditions that trigger a field visit or further analysis. Keep the plan small enough to test, then revise it using the results of real inspections. A useful monitoring workflow improves because its assumptions are examined systematically, and its observations remain connected to decisions throughout the process.
Sources & further reading
Explore the bhumisat spacecraft concept and our vision towards 2030, or return to the journal.